The site is live, every page opens fine in the browser, and Google shows none of it. The usual advice is "write more content" or "add keywords". But very often the problem never reaches content: Google hasn't seen the page, couldn't read it, or the site itself told it not to index it.
This post looks at the problem from a developer's side: where the pipeline breaks and how to find it with Search Console and a few commands. The examples are real, from the Search Console reports of this very site, where the first check showed roughly half of the known URLs not indexed.
First: where in the pipeline is it stuck?
Before a page appears in results it passes five stages, and each can fail on its own:
- Discovery: Google has to know the URL exists, from internal links, other sites or the sitemap.
- Crawl: Googlebot requests the page and gets a response. robots.txt, server errors and redirects matter here.
- Render: Google runs the page like a browser to see the real content. If CSS or JavaScript is blocked, what it sees differs from what users see.
- Index: Google decides whether to keep the page.
noindex, canonical tags and duplication decide this. - Ranking: only here do content, keywords and authority start to matter.
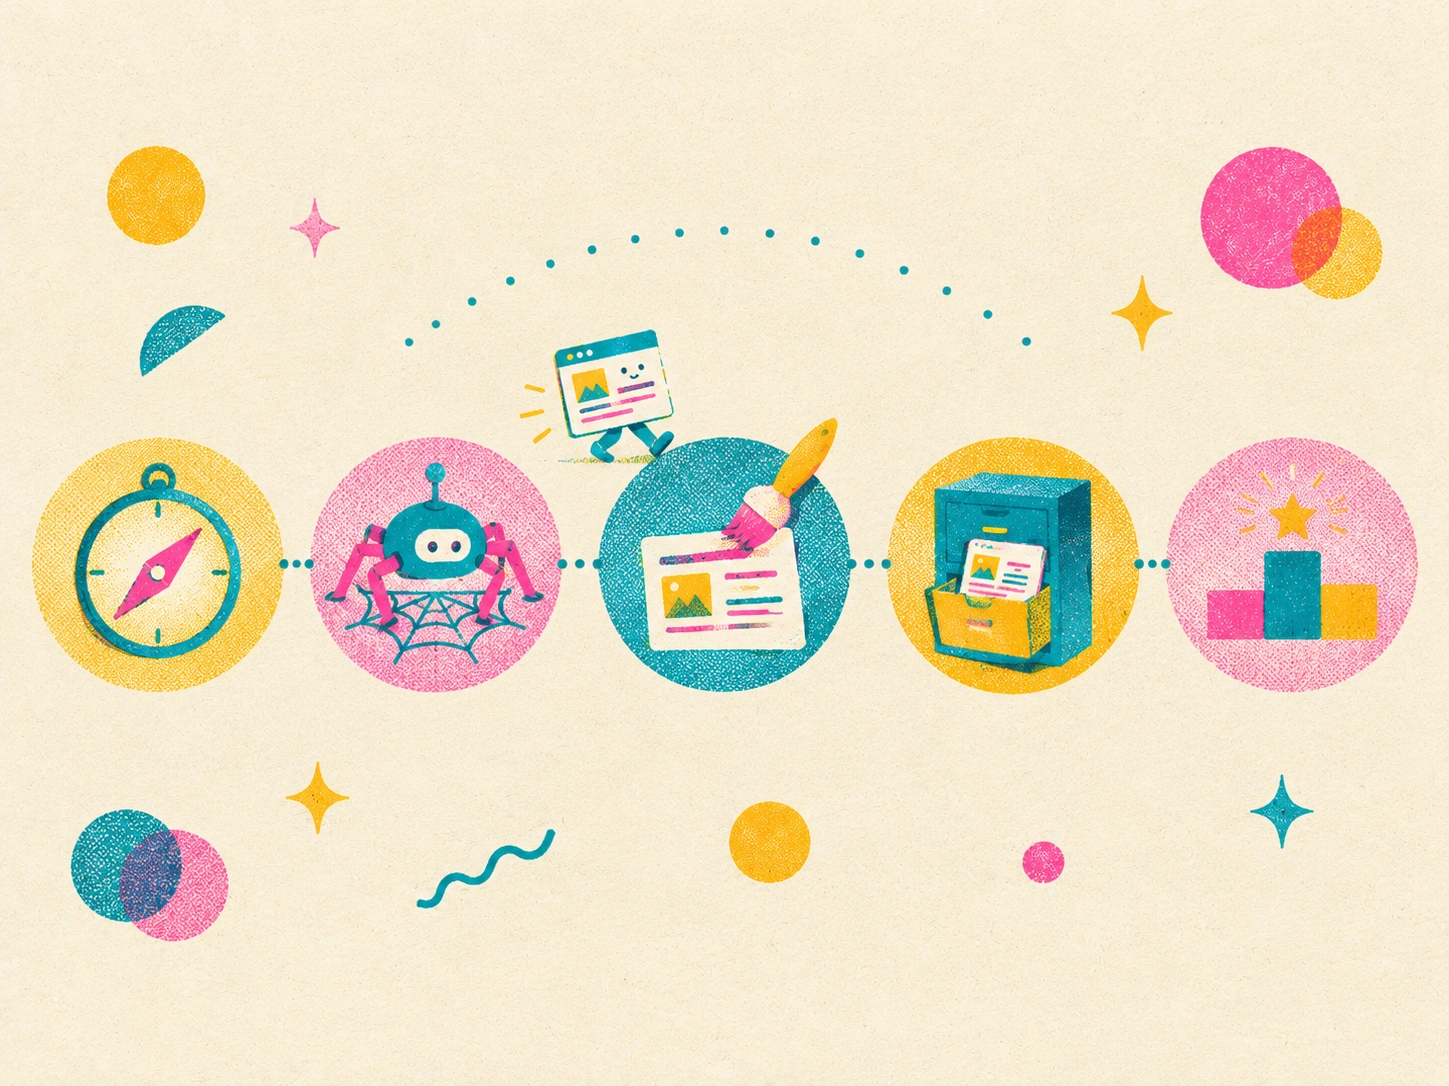
Most SEO advice is about stage five. If a page is stuck at stage two, the best content in the world stays invisible. So find the stage first.
The main tool: the Pages report in Search Console
A site:example.com search is a rough estimate and gives no reasons. The precise source is Indexing › Pages in Google Search Console, which lists a reason for every non-indexed URL. For a single URL, URL Inspection shows when Google last came, what response it got and which canonical it chose.
The most common reasons, and what they actually mean:
| Search Console message | Meaning | Serious? |
|---|---|---|
| Page with redirect | The URL redirects elsewhere | Usually not; the target gets indexed |
| Not found (404) | The URL no longer exists | Depends on whether anything links to it |
| Blocked by robots.txt | You stopped the crawl yourself | Yes, if unintended |
| Excluded by 'noindex' tag | The page asked not to be indexed | Very, if unintended |
| Duplicate without user-selected canonical | Google saw similar versions and picked one itself | Fix the canonical |
| Discovered – currently not indexed | Known, but not crawled yet | Normal on a new site, but a sign of low priority |
| Crawled – currently not indexed | Crawled and read, but not kept | Usually quality or duplication |
| Server error (5xx) | The server failed when Google came | Yes; repeated, Google crawls less |
Now the technical causes behind these messages, in pipeline order.
1. robots.txt blocks too much
robots.txt tells crawlers where not to go. The trouble starts when a harmless-looking line blocks something Google needs to render.
This site's robots.txt had Disallow: /_next/, meant to keep Next.js internals out of results. But the site's CSS, JavaScript and fonts load from exactly that path. Search Console reported the site's font as "Blocked by robots.txt": Google was seeing pages without the resources needed to build them. The fix was deleting one line.
Rule: never block static assets (CSS, JS, fonts, images) in robots.txt. And robots.txt is not a way to hide a page: a blocked page with links pointing to it can still appear in results without content. Use noindex for that.
2. A leftover noindex
The most common and quietest cause: the site was built on staging with noindex so Google wouldn't see the half-finished version, and the setting shipped to production. The page is perfectly healthy; it just tells Google not to keep it.
noindex can live in two places, and both need checking:
# in the HTML
curl -s https://example.com/page | grep -i "noindex"

# in the HTTP header (invisible in the page source)
curl -sI https://example.com/page | grep -i "x-robots-tag"
The second is the one people forget: a server config (nginx, say) or a plugin can add X-Robots-Tag: noindex to every response with no trace in the page source.
3. Wrong canonicals and duplicate versions
To Google, example.com/page, example.com/page/, http://example.com/page and example.com/page?utm_source=x can be four separate pages. The canonical tag says which is the original.
Two common mistakes:
- Every page's canonical points to the home page, usually from a shared layout or component that doesn't receive the current URL. To Google, the whole site becomes one page.
- No canonical at all, so Google picks among the versions itself, sometimes the one you don't want.
This site's report listed an old trailing-slash URL as "Duplicate without user-selected canonical", left over from the previous site structure. A permanent redirect from trailing-slash URLs plus a correct canonical on every page resolves that category.
For a bilingual site hreflang matters too: each Persian page should point to its English version and vice versa, or Google may treat one as a duplicate of the other.
4. Content built only with JavaScript
If the page ships as near-empty HTML and all text is fetched and built later by JavaScript, Google has to render the page to see any content. It does, but rendering is a separate, expensive step that can be delayed, and any JavaScript error means an empty page.
A simple test:
curl -s https://example.com/blog/my-post | grep -c "a sentence from the post"
0 means the text isn't in the initial HTML. For pages meant to rank (articles, products, case studies), server rendering or static generation (SSR, SSG or ISR in Next.js) removes the problem at the root. That's why this site renders its pages on the server and regenerates them after every content change.
5. Server errors exactly when Google comes
A site that opens for you can fail for Googlebot: the server slows down under load, a firewall or rate limiter blocks bots, or a dependency goes down.
An example from this site: the Next.js frontend fetched data from the Django backend through the site's public address. One day the server's internet connection had problems, the server could no longer reach its own public address, and the whole site returned 500, while frontend and backend were both healthy and running side by side on the same machine. The fix was connecting the frontend to the backend over the internal route.
An occasional error rarely matters, but repeated 5xx responses make Google slow its crawl, and pages get indexed later. Server logs for Googlebot requests, or Settings › Crawl stats in Search Console, show exactly what Google received.
6. Old URLs and deleted pages
After a redesign or a URL change, Google still knows the old addresses. If they return 404, whatever credit they had is lost.
This site's report showed URLs like /en/index.html, from the old static version of the site, still being crawled and returning 404. More interesting: an old blog post that had been deleted was still getting impressions in Google, even for a Spanish query. A page we thought didn't matter had real demand. It came back at the same URL.
Rule: before deleting or moving a page, check its impressions in Search Console. If it has any, keep the URL or 301-redirect it to the closest replacement.
7. "Discovered – currently not indexed": Google hasn't come yet
Google knows the URL (usually from the sitemap) but hasn't prioritised crawling it. On a new site or a low-authority domain this is normal. In this site's first check, most of this category were English versions of pages that Google had never crawled once.
What actually helps:
- Internal links: a page that only exists in the sitemap, with nothing linking to it, looks unimportant. Link to it from main pages and related posts.
- A clean sitemap: only final, indexable URLs (no redirects, no 404s, no noindex), with a real
lastmod. - Request indexing in URL Inspection for important pages; it is rate-limited, so save it for those.
- External links: one link from a credible profile or site raises crawl priority.
- IndexNow for Bing and a few other engines: announce each publish or change yourself instead of waiting for a crawl. Google doesn't support IndexNow, but Bing also feeds several AI assistants' search.
And patience. On a new domain, moving from "Discovered" to "Indexed" can take weeks.
A diagnostic checklist
When a page isn't in Google, go in this order:
- URL Inspection in Search Console: does Google know the URL? When was the last crawl? What does it say?
- Status code:
curl -sIshould return200; no redirect chain, no 404, no 5xx. - robots.txt: neither the path nor its CSS and JS are blocked.
- noindex: both in the HTML and in the
X-Robots-Tagheader. - canonical: points to this page, not the home page or another version.
- Content in the initial HTML: search a sentence of the text with
curl. - Sitemap and internal links: the page is in the sitemap and at least one other page links to it.
If all of that is fine and the page still isn't indexed, that's the moment to look at content and quality.
Conclusion
"My site isn't on Google" isn't one problem; it's a shared name for several different problems, each at a different stage of the pipeline. Most of them are technical, and a developer can find them in minutes with Search Console and a few curl commands. I've hit nearly every problem in this post on this very site, and none of them would have been solved by "more content".